Recognise first, or extract now? One check tells you which tool
OCR creates text in a scanned PDF; Extract Text pulls existing text out as TXT or Markdown. The select-all check and when to run both.
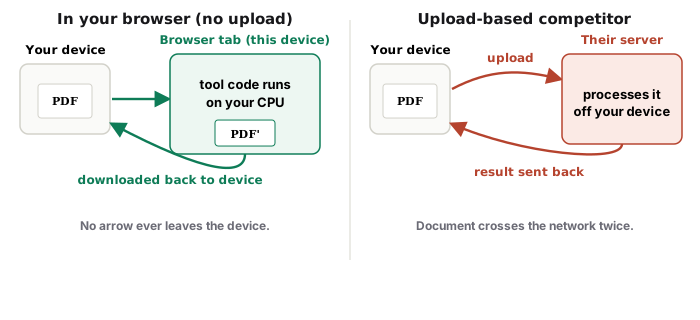
UnboundPDF is a free suite of 54 PDF and image tools that run entirely in your browser — merge, split, compress, edit text, OCR in 126 languages, redact, sign, convert and archive to PDF/A. Your document is read and written by the page on your own device; there is no document-upload endpoint in the core tools, no account, no watermark and no daily cap. Every result can be checked — with the Network tab, or with the Document Passport the Workspace writes for a chain of steps.
The check. Open the PDF in any reader and try to select a word. Nothing selects — it is a scan: run OCR PDF first. Text selects — run Extract Text now.
| OCR PDF | Extract Text | |
|---|---|---|
| Input | Scanned pages (pictures) | PDFs that already contain text |
| Output | The same PDF with a searchable text layer | A .txt or .md file |
| Accuracy | Depends on scan quality; per-page confidence shown | Exact — the document's own text |
| Then | Extract, convert to Word/Excel, search | Paste, search, feed a script |
Running both
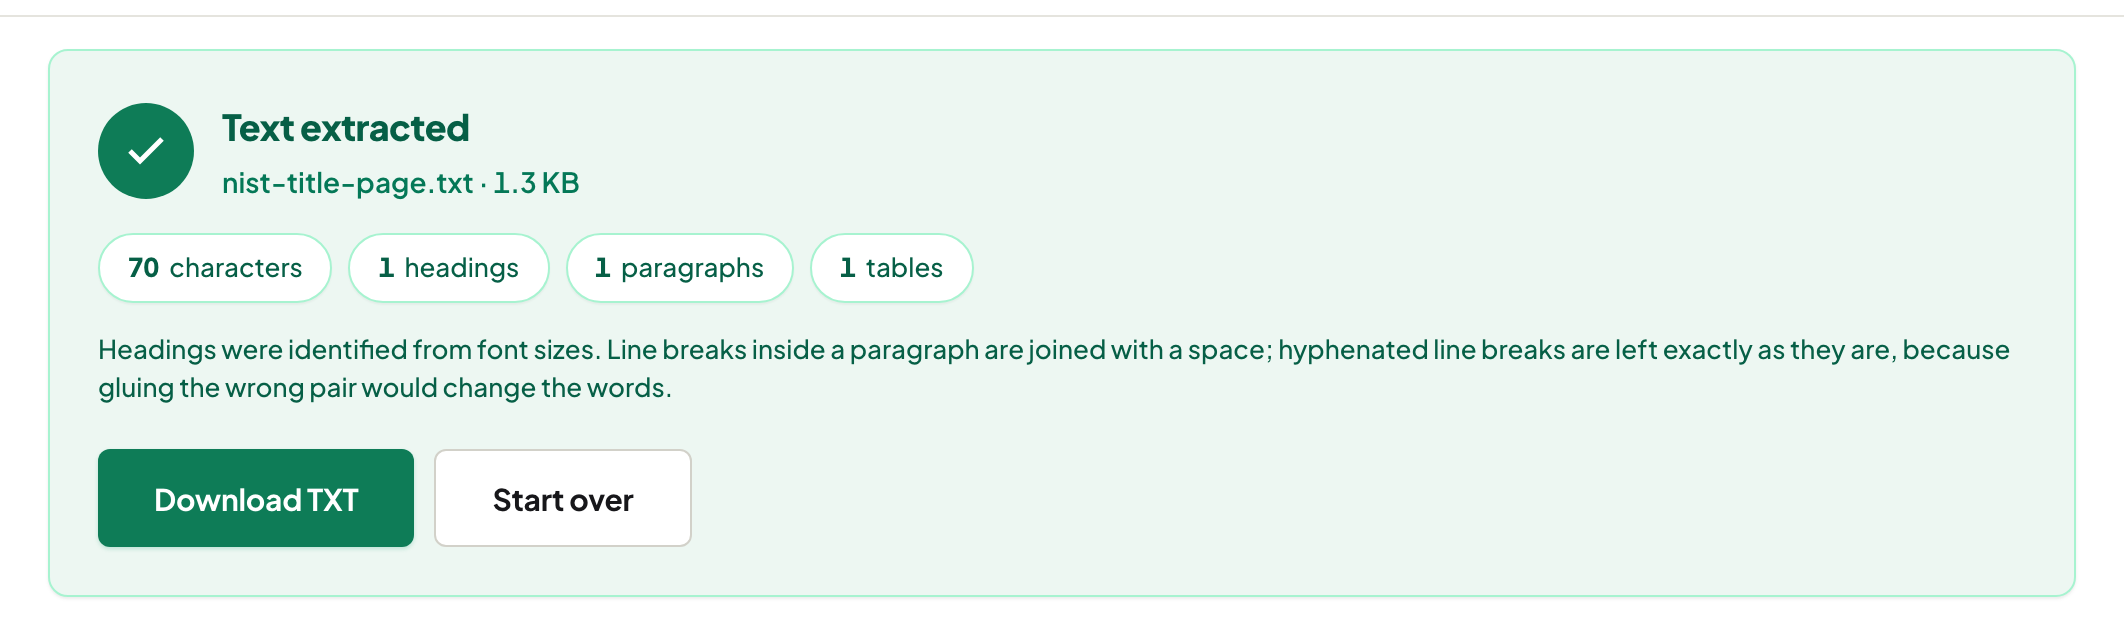
Scan → OCR → Extract Text is the normal path for paper documents: recognise on your device in one of 126 languages, then export the text in reading order with headings where the layout supports them. Check the confidence before trusting a number.
What OCR does not change
The page still looks like the scan; the text layer is invisible underneath. Nothing is re-encoded.
Word or Excel instead of text
For an editable document, PDF to Word; for a table with typed cells, PDF to Excel — both after OCR on a scan.
Frequently asked questions
Can Extract Text read a scan?
No — a scan has no text until OCR writes the layer.
Does OCR replace my scan with typed text?
No. The scan stays as the picture; text is added underneath for search and copy.
Which is uploaded?
Neither — both run in your browser; OCR downloads its engine once as program code.
Try it yourself
Free, private, no account. Runs entirely in your browser.